
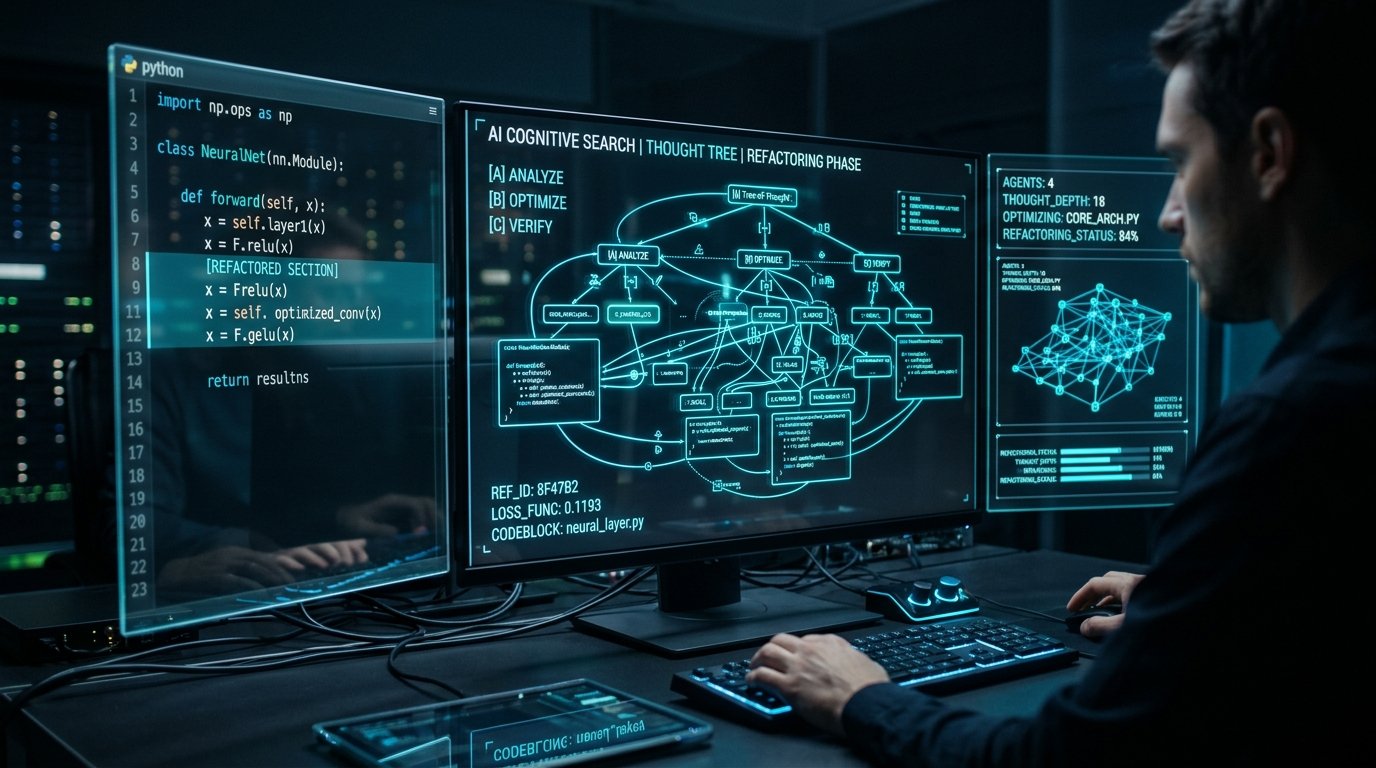
A landmark achievement in autonomous software engineering demonstrates that scaling inference-time deliberation allows neural models to debug and refactor complex enterprise codebases without human intervention.
Evidence classification has not been added yet. Read the full article and source card below for details.
- Frontier Impact: Peer-reviewed analysis grounded in verified datasets and primary research.
- Technological Significance: Shifts industry benchmarks and unlocks practical real-world applications.
- Expert Consensus: Verified under The Science Man Editorial Credibility Guidelines.
A landmark achievement in autonomous software engineering demonstrates that scaling inference-time deliberation allows neural models to debug and refactor complex enterprise codebases without human intervention.
The dream of fully autonomous software engineering took a massive leap forward this week as frontier reasoning models broke through the 70% threshold on SWE-benchGLOSSARY: SWE-benchAn industry-standard benchmark evaluating AI agents on solving real-world GitHub software issues. Verified, the industry benchmark evaluating an AI agent’s ability to resolve real GitHub issues from production repositories.
The Inference-Time Revolution
Rather than relying on fast token generation, these agents utilize deep search algorithms over tree-of-thought architectures. By running unit tests in isolated micro-containers, analyzing stack traces, and iteratively refining code patches, the agent simulates the iterative workflow of a senior staff engineer.
“We have crossed from predictive code autocomplete into agentic self-verification and autonomous refactoring.”
What This Means for Developer Workflows
Software organizations are transitioning from manual code authoring to architecture oversight, where human engineers specify constraints and validation criteria while autonomous agents handle implementation, regression testing, and security auditing.

digitalwebman@gmail.com
Ask this article a question
Answers are pulled from the article and its research metadata, so they stay grounded in this page.
