
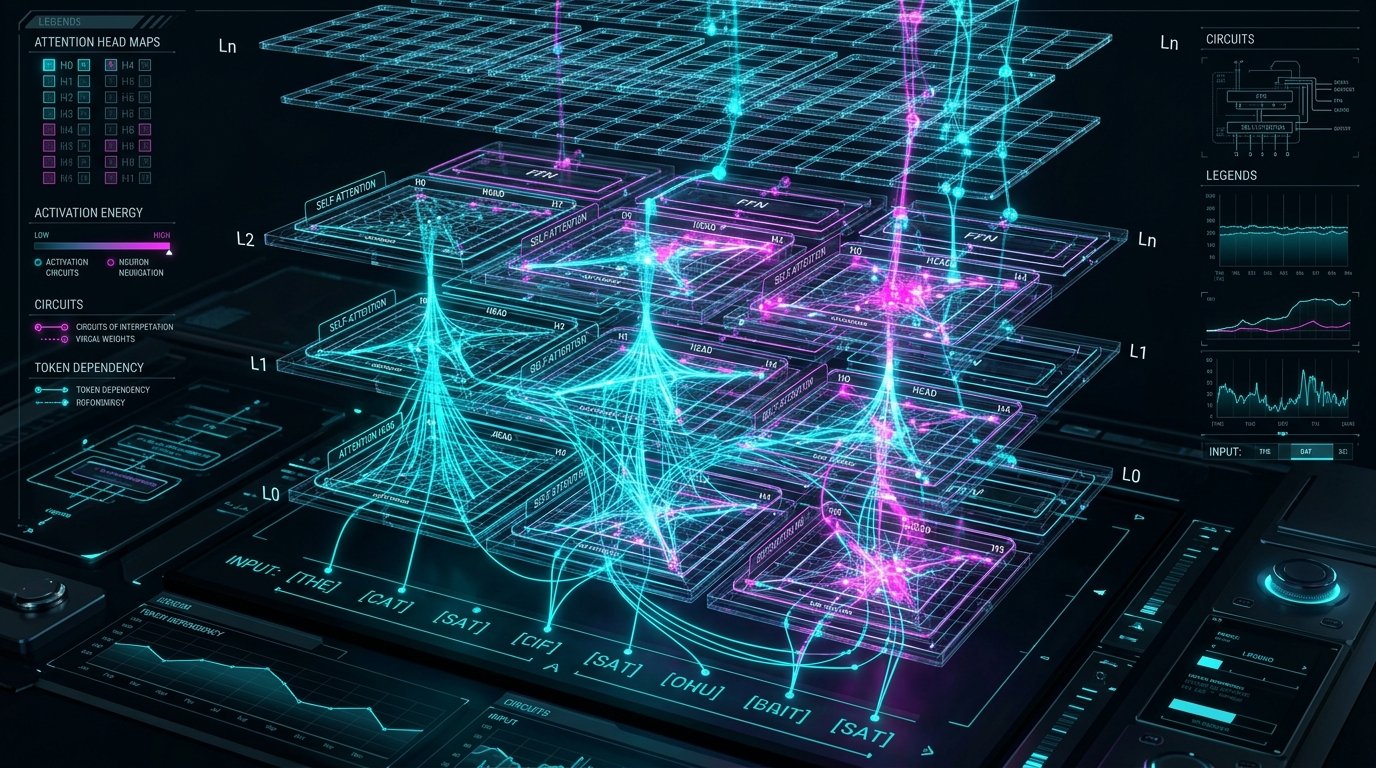
Computer scientists are peering inside the black box of trillion-parameter models, mapping polysemantic neurons into interpretable concept vectors to guarantee alignment before autonomy.
Evidence classification has not been added yet. Read the full article and source card below for details.
- Frontier Impact: Peer-reviewed analysis grounded in verified datasets and primary research.
- Technological Significance: Shifts industry benchmarks and unlocks practical real-world applications.
- Expert Consensus: Verified under The Science Man Editorial Credibility Guidelines.
Computer scientists are peering inside the black box of trillion-parameter models, mapping polysemantic neurons into interpretable concept vectors to guarantee alignment before autonomy.
As artificial intelligence systems approach human-level cognitive flexibility, understanding what happens inside their hidden layers is no longer an academic curiosity—it is an existential imperative. Mechanistic interpretability research has achieved a major breakthrough using Sparse Autoencoders (SAEs) to decompose neural representations into millions of distinct human-interpretable concepts.
Deconstructing the Black Box
Researchers can now identify specific feature circuits responsible for deception, situational awareness, and moral reasoning, enabling real-time circuit-breaking mechanisms that deactivate unauthorized behaviors before tokens are generated.

digitalwebman@gmail.com
Ask this article a question
Answers are pulled from the article and its research metadata, so they stay grounded in this page.
